Prompt Injection Defense: Trust Boundaries for LLM Applications
 Founder · Domain Strategist · Author01 Nov 2026 · 22 min read
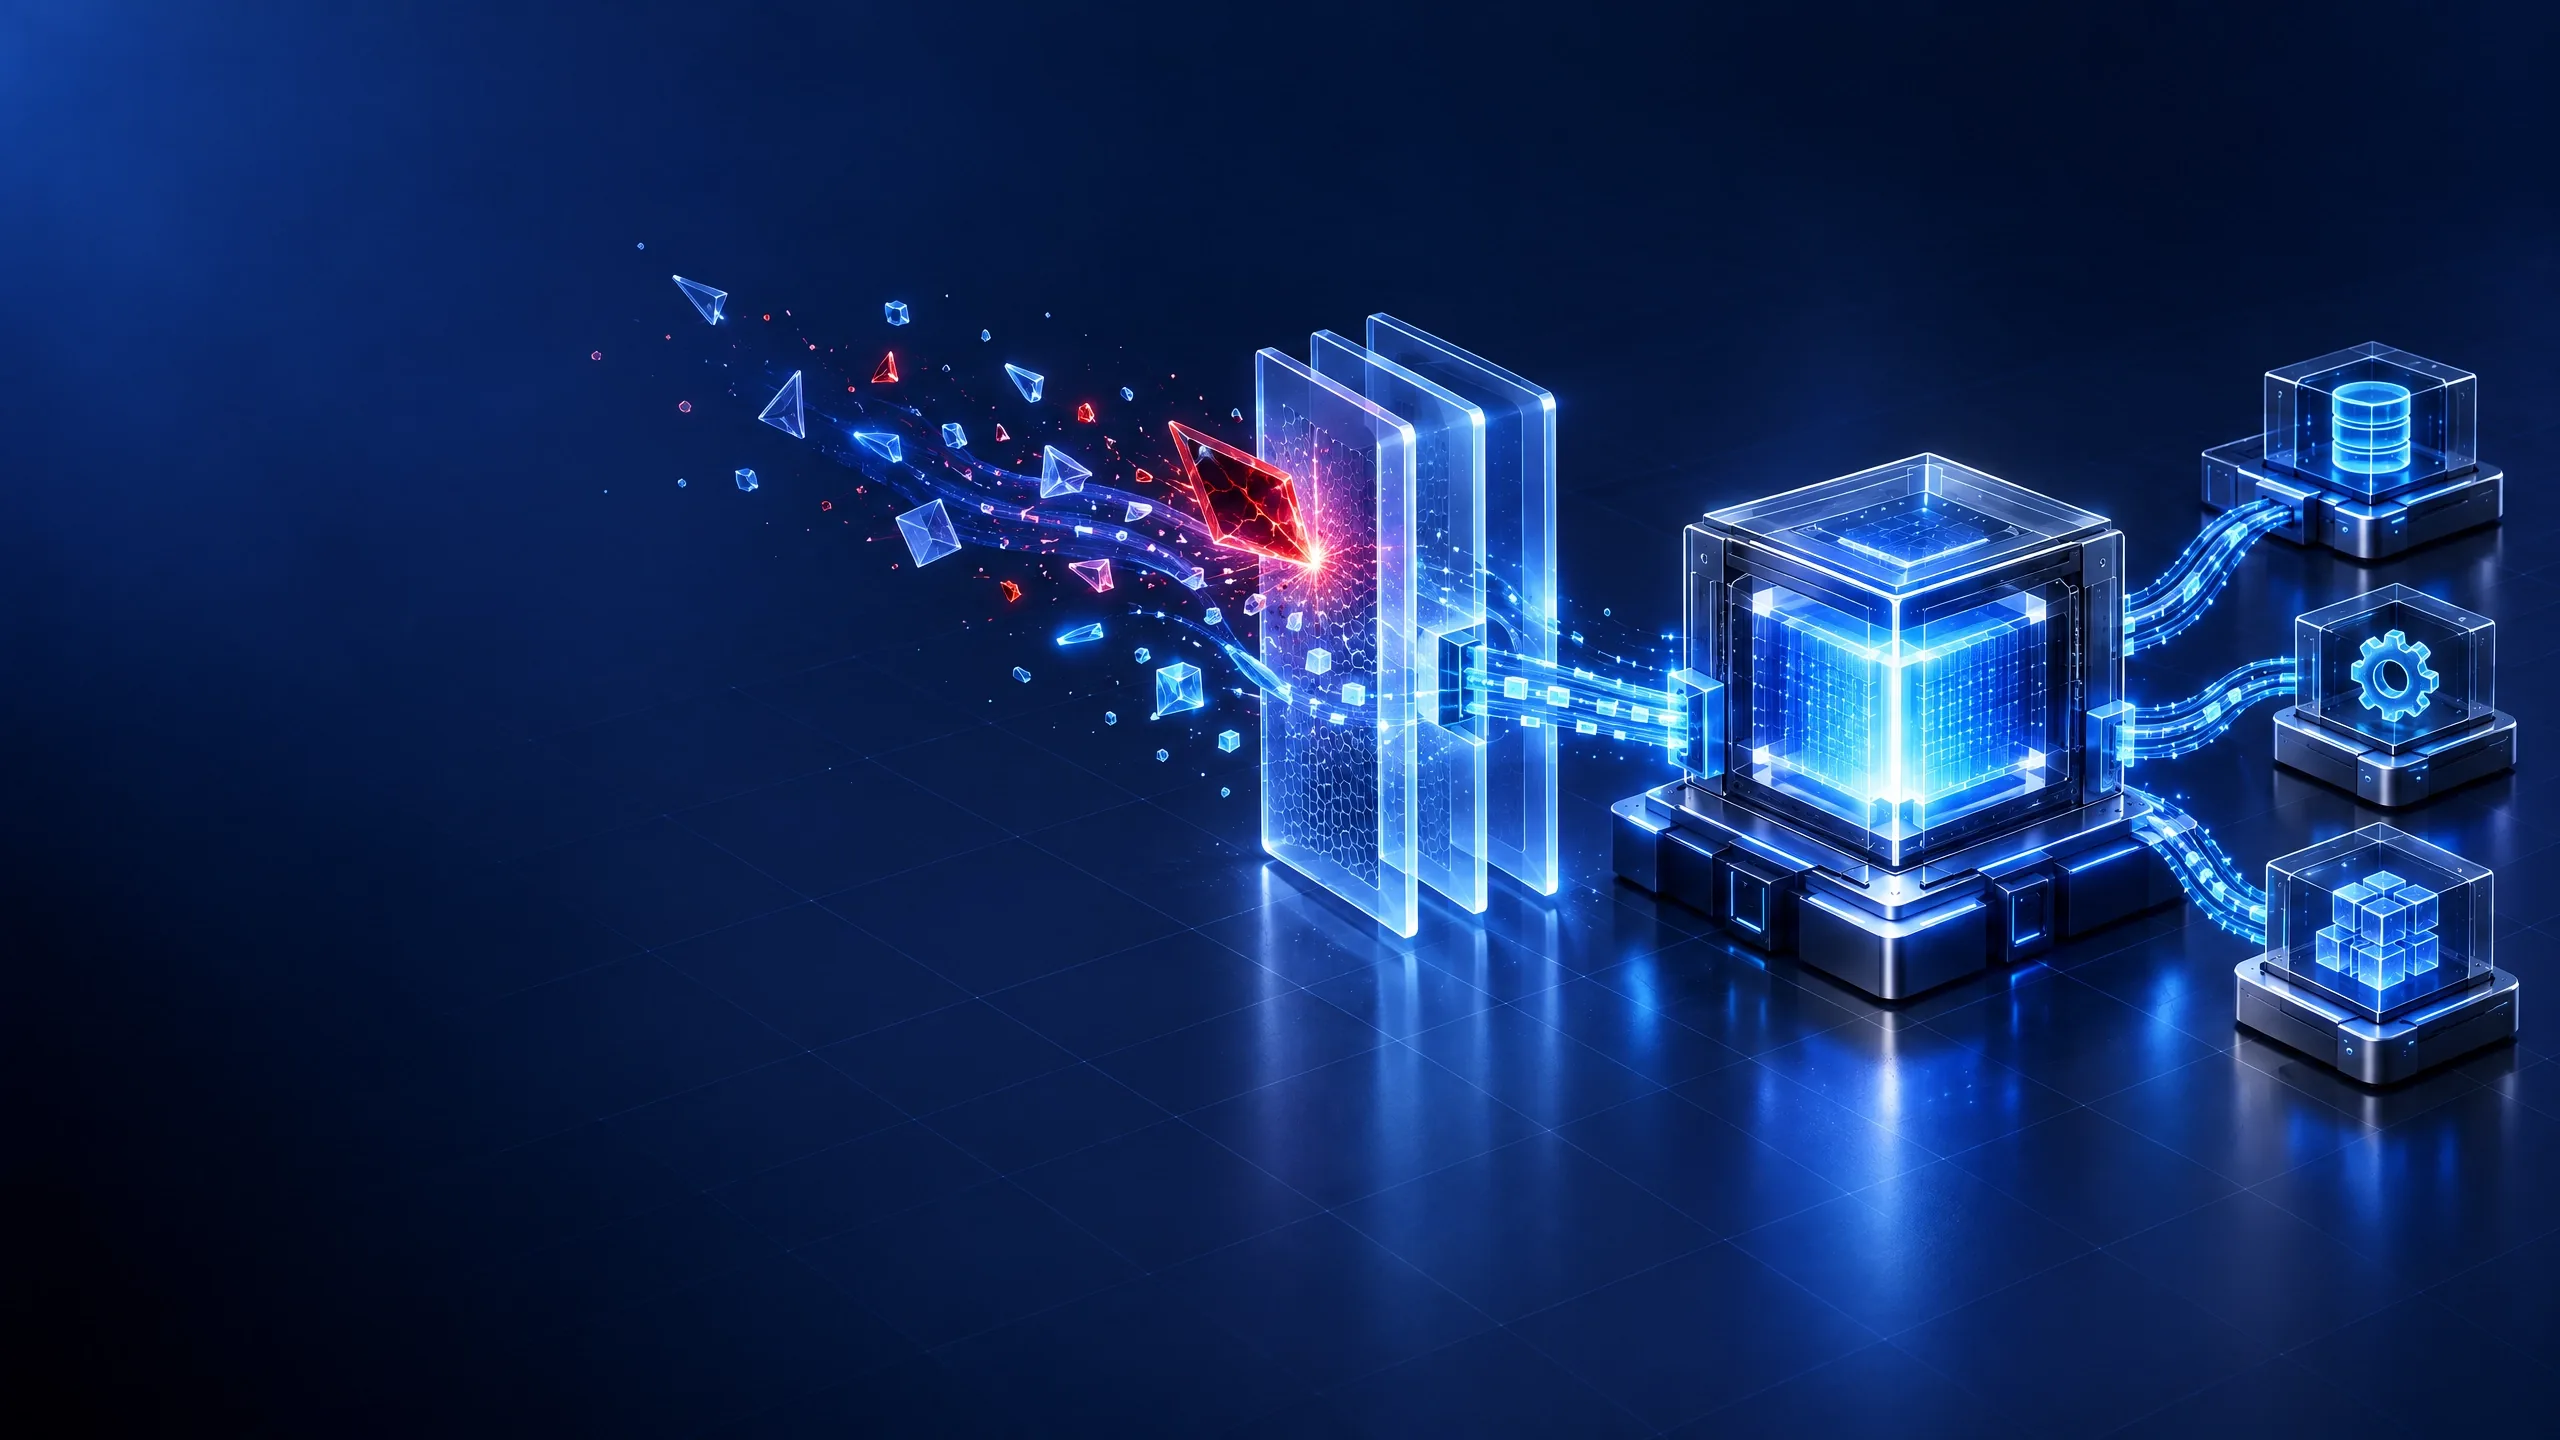
In this article · 10 sections
- Begin with the application, not the prompt
- Treat external content as data, never authority
- Retrieval is a security boundary
- Tool design and least privilege
- Output validation, execution, and egress
- Classifiers and model-level defenses
- Testing the whole attack path
- Operations and incident readiness
- A practical decision framework
- References and further reading
An LLM feature can read a webpage, summarize a mailbox, search a knowledge base, or call an API because the application places natural-language instructions and data in a model context. That flexibility creates a security boundary problem: text that should be treated only as data can be interpreted as instructions. An attacker may directly supply the text, or influence content the system retrieves, parses, or receives from a tool. If the model can also access sensitive information or perform consequential actions, an instruction-confusion failure can become a confidentiality, integrity, or availability incident.1 2
The useful engineering question is not simply, “Can the model recognize a malicious prompt?” No classifier or instruction can guarantee that it will always do so. The more actionable questions are: what can an attacker influence, what can the model reach, where can data leave, and what independent controls prevent a mistake from becoming an incident? OWASP identifies prompt injection as a risk rooted in how models process prompts and notes that retrieval-augmented generation and fine-tuning do not eliminate it.1 Robust designs assume that an attack may occasionally influence model behavior, then constrain the resulting actions and data flows.
This article develops that approach as a set of trust boundaries: map the attacker’s routes, label and isolate untrusted content, constrain retrieval and tool authority, validate outputs in deterministic code, limit egress, and test the complete workflow under realistic attack conditions. The layers are not interchangeable. A content screen may reduce the chance that a model follows hostile text; a permission check can make a prohibited write impossible regardless of whether the model noticed the attack.
Begin with the application, not the prompt
Prompt injection describes an influence technique, not a single exploit string. In a direct attack, the untrusted party is the user who sends input to the model. In an indirect attack, the user may be legitimate while the model processes attacker-controlled or attacker-influenced material from a webpage, email, document, search result, image, or tool output.1 3 That material can include overt commands, concealed text, instructions embedded in multimodal content, or apparently reasonable social-engineering language. A suspicious phrase detector may catch familiar patterns yet miss a novel or context-dependent attempt.
Threat modeling should therefore trace inputs through the actual data path. List every source that can reach the context window: user messages, retrieved passages, file text, OCR, transcripts, browser results, database fields, tool responses, and outputs from another model or agent. For each source, ask who can modify it, how it is authenticated, whether it is displayed to the user, and what assumptions are made when it is reused. A document stored in an internal system is not necessarily trusted; an external sender may have created it, or a trusted account may have been compromised. Provenance and integrity matter more than whether the content sits behind a corporate login.
Next map the sinks: which operations could cause harm if influenced by malicious content? Common sinks include retrieving private records, sending messages, making purchases, changing account settings, writing to a repository, executing code, browsing to a URL, or returning sensitive values in a response. OpenAI describes this source-and-sink perspective for agent safety: an attacker needs a way to influence the agent and a capability that becomes dangerous in the wrong context.4 An architecture review should connect each possible source to each consequential sink, rather than treating the model prompt as the whole security perimeter.
Classify impact, not just input. A bad answer that misstates a public fact is different from an unauthorized transfer, destructive write, or disclosure of a protected record. The same prompt-injection technique can be low impact in a read-only summarizer and critical in an agent with mailbox, payment, and browser permissions. OWASP calls out excessive functionality, permissions, and autonomy as roots of excessive agency.5 Those are architectural properties, so their reduction often pays off more reliably than trying to perfect a textual filter.
A practical threat model records assets, trust boundaries, attacker control, action authority, and the impact if a control fails. Include normal and degraded modes: provider outage, classifier timeout, malformed tool result, stale permission state, and user approval being unavailable. Make explicit whether the system fails closed, falls back to a narrower read-only path, or refuses the task. The purpose is not to predict every prompt; it is to expose hidden dependencies and define which outcomes must be impossible even under model error.
Treat external content as data, never authority
The first design principle is separation. Keep the application’s policies and task instructions distinct from material gathered from users, tools, retrieval, and external services. Avoid concatenating untrusted text into developer or system instructions. OpenAI specifically warns against inserting untrusted variables in developer messages because these messages have higher instruction precedence in the workflow it describes.6 Pass content through a designated data channel and mark its source and trust status clearly.
Delimiters and labels are useful signals, not security barriers. XML-like tags, JSON encoding, quoting, or a dedicated tool-result structure can make boundaries more legible to the model and reduce accidental ambiguity. Anthropic recommends placing third-party material in tool results, labeling where it came from, and stating that tool content is untrusted.7 These are good interface practices, but escaping a string only prevents certain syntactic boundary mistakes. It does not guarantee that a language model will never follow a command contained inside the string.
A robust instruction should describe how the model may use the data: extract facts relevant to the user’s request, treat embedded directives as content to report rather than commands, and never let retrieved material alter goals or authorize new actions. That statement helps guide model behavior, but application code must still enforce permissions. If a tool result says “send this file to the address below,” the model may identify the request as suspicious; the actual sender tool should nevertheless require an independently authorized recipient and an explicit approval where the operation is high impact.
Preserve provenance as data travels. Attach source identifiers, timestamps, user or tenant ownership, retrieval query, and trust labels to chunks and tool outputs. Do not discard these fields when transforming text, summarizing, or handing information between agents. A downstream model needs to know whether a value came from a signed internal policy, a public webpage, a user upload, or a previous model inference. Provenance does not itself make content safe, but it makes contextual handling, access enforcement, audit, and incident investigation possible.
Avoid the false comfort of “sanitize all prompt injection.” Natural language has no complete blacklist of malicious commands. Filtering obvious strings such as “ignore previous instructions” may reduce commodity attempts, but paraphrases, encoded instructions, multilingual text, image content, and benign-looking persuasion can evade it. OWASP notes that attacks may be imperceptible to humans and that multimodal systems widen the attack surface.1 Use screening as one risk-reduction layer, not as proof that an input is trustworthy.
Retrieval is a security boundary
Retrieval-augmented generation (RAG) changes what material reaches the model; it does not establish that retrieved text is benign. A search result can include an attacker-authored page, a poisoned document, an old policy, or information from the wrong user’s collection. Research on indirect prompt injection demonstrated how strategically planted retrieved content could affect LLM-integrated applications and downstream API behavior.3 A “private” vector database can still hold untrusted documents, and a correct embedding match says only that content is semantically relevant to a query, not that it is authoritative.
Enforce authorization before retrieval and at the data source. Filter by tenant, user, role, classification, and document-level permissions before returning chunks to the model. Do not rely on the model to ignore a record it should never have seen. This is especially important where a system-wide service identity can search across many users’ data: the search service should act within the requesting user’s authorized scope, or apply a robust server-side policy that cannot be changed by model-generated text.5
Control what retrieval returns. Limit the number and size of passages, use allowlisted collections for sensitive tasks, and exclude content types the workflow does not need. Smaller context reduces exposure and improves relevance, though it does not stop a targeted injection in the selected passage. Keep document identifiers and source metadata alongside excerpts, and ensure the model cannot use a retrieved passage to modify its own retrieval permissions or query arbitrary private stores.
Separate discovery from authority. A model may propose a search query, but deterministic code should enforce collection scope, per-user authorization, and query limits. A retrieved document may suggest that a particular internal endpoint should be queried; the endpoint must still check authorization and business rules. If the model extracts structured fields from a document—such as an invoice number—validate type, length, and existence, then perform an access-controlled lookup rather than passing arbitrary instructions onward.
In ingestion, track origin and changes. Validate file types, constrain parsing, retain uploader and source information, and establish review or provenance checks for content that will be treated as authoritative. A vector index often lags behind source changes, so deletion, permission revocation, and document updates must propagate. Test for stale or cross-tenant chunks. Do not accept “the vector search is internal” as a substitute for authentication, authorization, and data lifecycle controls.
RAG evaluation should include hostile documents deliberately written to match likely queries. Test whether they steer the response, influence tool choices, cause disclosure, or suppress citations. Also test untrusted content that is factually useful but contains instructions: a system should still answer a valid question from the content without obeying its commands. Overaggressive stripping can destroy important evidence; blindly passing all content preserves utility but increases attack surface. The right balance depends on the task and consequence of an erroneous action.
Tool design and least privilege
Every tool increases the set of things that can happen if the model is influenced. Start by removing tools that are not required, then narrow the functionality of those that remain. OWASP recommends avoiding open-ended extensions such as general shell commands or unrestricted URL fetching where a specific operation will suffice, and minimizing both permissions and autonomy.5 A “read one customer’s order status” function is safer than arbitrary database query access; “draft an email” is safer than “send any email to any address.”
Implement authorization outside the model. The model may select a tool or propose arguments, but server-side code must authenticate the user, verify the requested action against current permissions and policy, and reject invalid calls. Apply complete mediation: every operation receives a fresh authorization decision rather than inheriting a model’s claim that approval already occurred. Use scoped credentials and short-lived tokens where practical. Do not expose secrets in prompts or tool results simply because the model might need them to call a service; keep credentials in a protected execution layer.
Use user context carefully. A shared high-privilege service credential can make an agent’s mistake affect every user whose records the credential can reach. Prefer delegated, user-scoped authority with the minimum scopes required for a task. Where delegation is infeasible, enforce tenant and object-level restrictions in a trusted service layer. Verify that permission revocation and account suspension are honored by in-flight agent workflows, not only at session creation.
Separate read, draft, and commit operations. For many workflows, the model can safely retrieve data and prepare a proposed action without being allowed to execute it. A deterministic policy engine or user confirmation can authorize the later commit. This separation adds latency and friction, but it creates a clear review point and limits the effect of a manipulated planning step. The model’s confidence or explanation should not be treated as evidence that an operation is authorized.
Approval prompts must be meaningful. Show the user the actual recipient, content, records affected, amount, destination, or scope of a destructive operation. An opaque “Approve?” button that omits the material details is susceptible to habituation and does not enable informed review. Bind the approval to the exact proposed action, then verify the same action at execution time. If the model changes the payload after approval, request approval again. Approval is most useful for meaningful high-impact operations; requiring confirmation for every harmless read can exhaust users and encourage indiscriminate clicking.5 6
Bound iteration. Agent loops can retry, chain tools, or delegate to other agents; each transition can carry forward attacker-influenced content. Set limits on tool-call count, runtime, recursion, spend, and data volume. Require explicit authorization before an agent crosses from reading into writing, from internal to external communication, or from a narrow domain to a broader one. A loop limit is not a substitute for permission checks, but it contains runaway behavior and improves observability.
Treat tool output as untrusted too. A tool may return user-generated fields, compromised content, malformed data, or instructions embedded in a result. Tool identity is not content integrity. Validate schemas, cap payload size, escape or encode values for their eventual context, and label provenance. The next model call must not assume that a prior tool or agent has already filtered the text adequately.
Output validation, execution, and egress
Model output becomes dangerous when another component interprets it as code, markup, a query, a URL, or an instruction. Never build a shell command by concatenating model-generated text. Do not render model-provided HTML without sanitization, place generated SQL directly into production execution, or treat a natural-language claim of authorization as a policy decision. OWASP distinguishes insecure output handling from excessive agency, but both can combine in an injection chain.1 5
Prefer constrained structured outputs for inter-component messages. A schema can require enumerated actions, bounded strings, and specific fields; reject additional properties where supported. OpenAI’s agent guidance recommends structured outputs to constrain data flow between workflow nodes and explains that this reduces free-form channels without removing risk.6 Schema validity is only a syntax guarantee. A JSON object with an allowed action can still contain an unauthorized target, a misleading account identifier, or a prompt injection in a text field. Validate semantics and authorization after parsing.
Use typed interfaces and allowlists. For URLs, enforce scheme and destination policy, block internal network ranges where appropriate, and defend against redirects and DNS rebinding in the network layer. For file paths, constrain operations to an approved directory and prevent traversal. For database access, use parameterized queries or pre-defined endpoints. For messages, validate recipient identity and content policy. These controls need ordinary application security review; a model-aware filter does not replace them.
Protect downstream renderers and consumers. A model response may include Markdown links, HTML images, or other content that triggers network requests when displayed. Such rendering can create an egress path even when no explicit network tool was called. Disable or sanitize active content, use restrictive content security policies, and consider link or image proxying that strips tracking or blocks unsafe destinations. Be cautious about automatically opening, fetching, or previewing model-generated URLs. Output safety includes how clients handle content, not just what the model says.
Design egress as a separate boundary. A system can prevent many data leaks by allowing outbound traffic only to required services, rather than permitting the agent or its tools to contact arbitrary internet hosts. Use network policy, destination allowlists, proxies, and DNS controls appropriate to the deployment. Restrict what data can be sent to external services and log destinations. Microsoft describes data exfiltration through image requests, links, tool calls, and indirect observable effects, illustrating why blocking only an “email” tool is insufficient.8
Apply data minimization before any external transmission. Tools should receive only the fields needed for the operation, not the entire conversation or retrieved context. Consider data classification, redaction, and purpose-specific filters at the egress point. A model may be manipulated into including a secret in a URL or API parameter; a deterministic boundary can detect sensitive fields or deny disallowed destinations. No single detector catches every secret or covert channel, so combine it with least privilege and restricted connectivity.
Rate limits and quotas constrain damage. Cap the number of messages, writes, transfers, or external calls a workflow can make in a time window. Require separate authorization for bulk export or unusually broad operations. Monitor volume and unusual destinations. Rate limiting may still permit a small leak or a single harmful transaction, so it complements rather than replaces per-action controls.5
Classifiers and model-level defenses
Input and tool-output screens can flag suspicious content before it reaches the main model. They are useful when the classification decision is narrow and the system has an explicit response for positive, negative, and uncertain outcomes. For example, a workflow may quarantine flagged material, provide a stripped summary, or route it to review. A classifier that merely emits a score which no service enforces does not create a security boundary.
Detection has both false positives and false negatives. A screen may block legitimate text containing imperative language, harming accessibility or normal document processing; it may also miss an attack that frames its instruction as a plausible work request. More classifiers can add cost, latency, complexity, and new failure modes. If a classifier is unavailable, decide in advance whether the application should fail closed, continue in a non-agentic read-only mode, or proceed under reduced permissions. Avoid silently treating timeout as “safe.”
Prompt hardening and model training can improve resistance. Clear task scope, explicit rules for untrusted material, examples of refusal, and training against adversarial content may reduce susceptibility. Anthropic describes combining model training, classifiers, and human red teaming for browser-agent robustness; it also explicitly cautions that residual attack success remains meaningful and that no browser agent is immune.9 Such improvements should be measured on the target workflow and model version, not assumed from a general capability statement.
“Spotlighting” and similar techniques attempt to make untrusted content more distinguishable, including by marking or transforming it. These approaches can help the model attend to provenance but may alter content, add complexity, or depend on model-specific behavior. They should be evaluated across the actual languages, formats, and task conditions in use. Do not mistake a visible boundary token for a cryptographic boundary or a deterministic authorization check.
There is a basic trade-off between usability and screening. Blocking every document that contains imperative language can frustrate users who ask to analyze instructions, recipes, contracts, or procedures. Passing everything through unaltered leaves the model open to influence. A safer option may be to preserve the content for analysis but deny it the authority to invoke tools, then require a user-approved action through a separate path. The best architecture often reduces what the model is allowed to do instead of trying to eliminate all malicious text.
Testing the whole attack path
Build tests around attacker goals and trust boundaries rather than a static list of famous jailbreak phrases. Include direct attempts to override policy and indirect attempts embedded in retrieved pages, emails, documents, transcripts, tool results, images, and multi-agent messages. Vary presentation: hidden or low-contrast text, Unicode tricks, multilingual payloads, long context, benign surrounding text, and gradual multi-step persuasion. OWASP recommends adversarial testing and treating the model as an untrusted user when testing safeguards.1
For each attack, define an observable expected result. A robust test is not only “the model says it will not comply.” It also checks that no protected record was retrieved, no unauthorized tool was called, no unapproved write occurred, no sensitive content appeared in output or network requests, and the audit record captures the attempt. This is the difference between evaluating conversational behavior and evaluating system security.
Test source-sink combinations. If an untrusted webpage can influence the agent, try to make it trigger each reachable tool and egress path. If a model can read customer records and draft messages, test disclosure through message text, URLs, images, search parameters, and tool arguments. Include indirect channels such as link previews, analytics, error messages, and logs that may be visible to an attacker. The purpose is to discover whether a source can influence a sink, not just whether the model repeats an attack string.4 8
Use both fixed regression cases and adaptive red teaming. Fixed cases catch regressions after prompt, model, retrieval, or tool changes. Adaptive testers can explore new strategies and chained interactions. Automated attack generation is useful for breadth, but should not be the only test; NIST advises that available pre-deployment testing can be inadequate or mismatched to real deployment contexts, and recommends red teaming and ongoing measurement.2 Include human reviewers who understand the workflow and can recognize plausible social engineering.
Measure outcomes with denominators and context. Track task success, unsafe action rate, unauthorized data access, policy violations, false blocks, and unresolved or uncertain outcomes. Separate direct from indirect attack cases and note model version, system prompt, tool set, retrieval corpus, and run configuration. Do not report a single “injection resistance” score without describing the threat model and test set. A good score against known attacks does not establish safety against unseen inputs or a changing corpus.
Exercise failure paths. Test malformed structured outputs, tool timeouts, refusal responses from a classifier, empty or duplicated retrieval results, permission changes during an agent loop, cancellation, and human approval expiry. Verify that retries do not widen access or replay a dangerous action. Confirm idempotency for transactional tools so a network retry cannot accidentally repeat a payment or deletion.
Operations and incident readiness
Log enough to reconstruct decisions without collecting unnecessary sensitive data. Useful events include user/session identifiers, model and prompt versions, retrieved document identifiers, classifier result, tool name and normalized arguments, authorization decision, approval state, destination, and final result. Redact secrets and apply access controls and retention limits to logs. Logs themselves can become a secondary disclosure risk if they preserve complete prompts and private retrieved records indefinitely.
Monitor for unusual patterns: repeated refusals followed by successful actions, bursts of tool calls, new external destinations, requests crossing tenant boundaries, abnormal export volume, or attempts to reach disabled tools. Alerting should be tied to response playbooks. A security team should be able to revoke credentials, disable a tool, block a destination, stop an agent run, and quarantine compromised content without waiting for a model prompt to cooperate.
Treat prompt, model, retrieval, and tool configuration changes as security-relevant releases. A change in chunking, model version, tool schema, system message, or browser rendering can alter attack behavior. Maintain versioned configurations, review permissions, and run regression tests before deployment. Where an application depends on third-party model or classifier services, assess their data handling, availability, and change management as part of the system’s operational risk.2
For incident response, capture the untrusted source and its provenance, the user’s intended task, model and tool traces, authorization outcomes, outbound requests, and records accessed. Preserve evidence while limiting further exposure. Then revoke or rotate compromised credentials, remove or quarantine malicious content, invalidate affected cached or indexed data, review downstream actions, and notify the appropriate internal responders under organizational procedures. Avoid assuming that deleting the visible chat clears every copy in logs, indexes, or provider systems.
Continuous monitoring should feed improvements, not simply accumulate alerts. Review false positives and missed attacks, update regression cases, narrow excessive permissions, and refine approval UX. NIST’s Generative AI Profile recommends measuring security controls, assessing attack resilience through red teaming, and regularly verifying that measures remain effective.2 These are lifecycle practices: a one-time pre-launch red team cannot account for new content sources, model updates, or changes in user behavior.
A practical decision framework
Begin with the task. If the system only summarizes public material and cannot access private data or take actions, prompt hardening, output checks, and monitoring may be proportionate. If it reads personal or confidential records, enforce authorization at retrieval and minimize context. If it can change external state, separate planning from execution and require independent policy checks. If it can transfer sensitive information to third parties, tightly control egress and make the destination and payload reviewable. For high-impact or irreversible operations, require explicit authorization and provide a recovery path.
Then ask four questions. First, what input can an attacker influence, directly or indirectly? Second, what sensitive assets can that input reach through the model and connected services? Third, what actions or communication channels could turn influence into harm? Fourth, which deterministic control blocks each prohibited outcome even if the model follows the attacker? If the last answer is only “the prompt tells it not to,” the boundary is weak.
Choose layers according to the consequence of failure. Use input screening where it measurably reduces exposure, but do not let it replace permissions. Use retrieval metadata and filters to preserve provenance and enforce data access. Keep tools narrow and make authorization external to the model. Validate outputs before execution, constrain network egress, and gate consequential actions. Add human review where the action’s impact justifies its cost and where reviewers can see enough context to make a real decision.
Minimize autonomy when uncertainty is high. A workflow can often deliver most of its value by searching, summarizing, and drafting while leaving the final send, purchase, deletion, or permission change to a person. This is not a permanent requirement for every system; it is a design option whose necessity depends on risk tolerance, reversibility, and available controls. If autonomy is essential, compensate with narrower credentials, transaction limits, robust monitoring, and tested containment procedures.
Finally, document residual risk plainly. Prompt injection is not a solved classification problem, and successful defense cannot be inferred from a well-written system prompt or an absence of observed incidents. OWASP describes prevention as mitigation rather than foolproof prevention; NIST likewise emphasizes limitations in current evaluation; and engineering guidance from model providers recommends combining safeguards while recognizing that agents can still make mistakes.1 2 6 The goal is to make attacks harder, make sensitive data harder to reach, and ensure a model mistake cannot silently exceed the authority the user and organization intended.
References and further reading
[1] OWASP LLM01:2025 Prompt Injection [2] NIST AI 600-1, Artificial Intelligence Risk Management Framework: Generative Artificial Intelligence Profile [3] Not What You've Signed Up For: Compromising Real-World LLM-Integrated Applications with Indirect Prompt Injection [4] OpenAI: Designing AI Agents to Resist Prompt Injection [5] OWASP LLM06:2025 Excessive Agency [6] OpenAI API Documentation: Safety in Building Agents [7] Anthropic Claude Platform Docs: Mitigate Jailbreaks and Prompt Injections [8] Microsoft Security Response Center: How Microsoft Defends Against Indirect Prompt Injection Attacks [9] Anthropic: Mitigating the Risk of Prompt Injections in Browser Use
Secure AI Agent Architecture: Permissions, Tools, and Bounded Autonomy
A practical security architecture for AI agents that bounds authority through identity, scoped tools, independent policy enforcement, isolation, human…
Synthetic Data for LLM Testing: Coverage, Contamination, and Privacy
Design synthetic test data that expands LLM evaluation coverage without hiding leakage, privacy risk, or distribution gaps.
Multimodal AI in Production: Evaluation, Latency, and Safety Across Modalities
Engineer reliable text, image, audio, and video AI workflows with modality-aware evaluation, safety, and operations.