Federated Learning in Practice: Privacy Limits, Security Risks, and System Design
 Founder · Domain Strategist · Author05 Nov 2026 · 35 min read
In this article · 13 sections
- Choose the federation that matches the data and participants
- How a training round works—and where choice enters
- Non-IID data is a first-order design constraint
- Secure aggregation: hiding individual contributions from the coordinator
- Differential privacy: quantify the information released
- Update leakage is a realistic threat, not a theoretical footnote
- Poisoning and backdoors: contributors can alter the model
- Communication, availability, and reproducibility
- A production evaluation plan
- Choosing deployment patterns
- Implementation checks and common failure modes
- The practical standard
- References
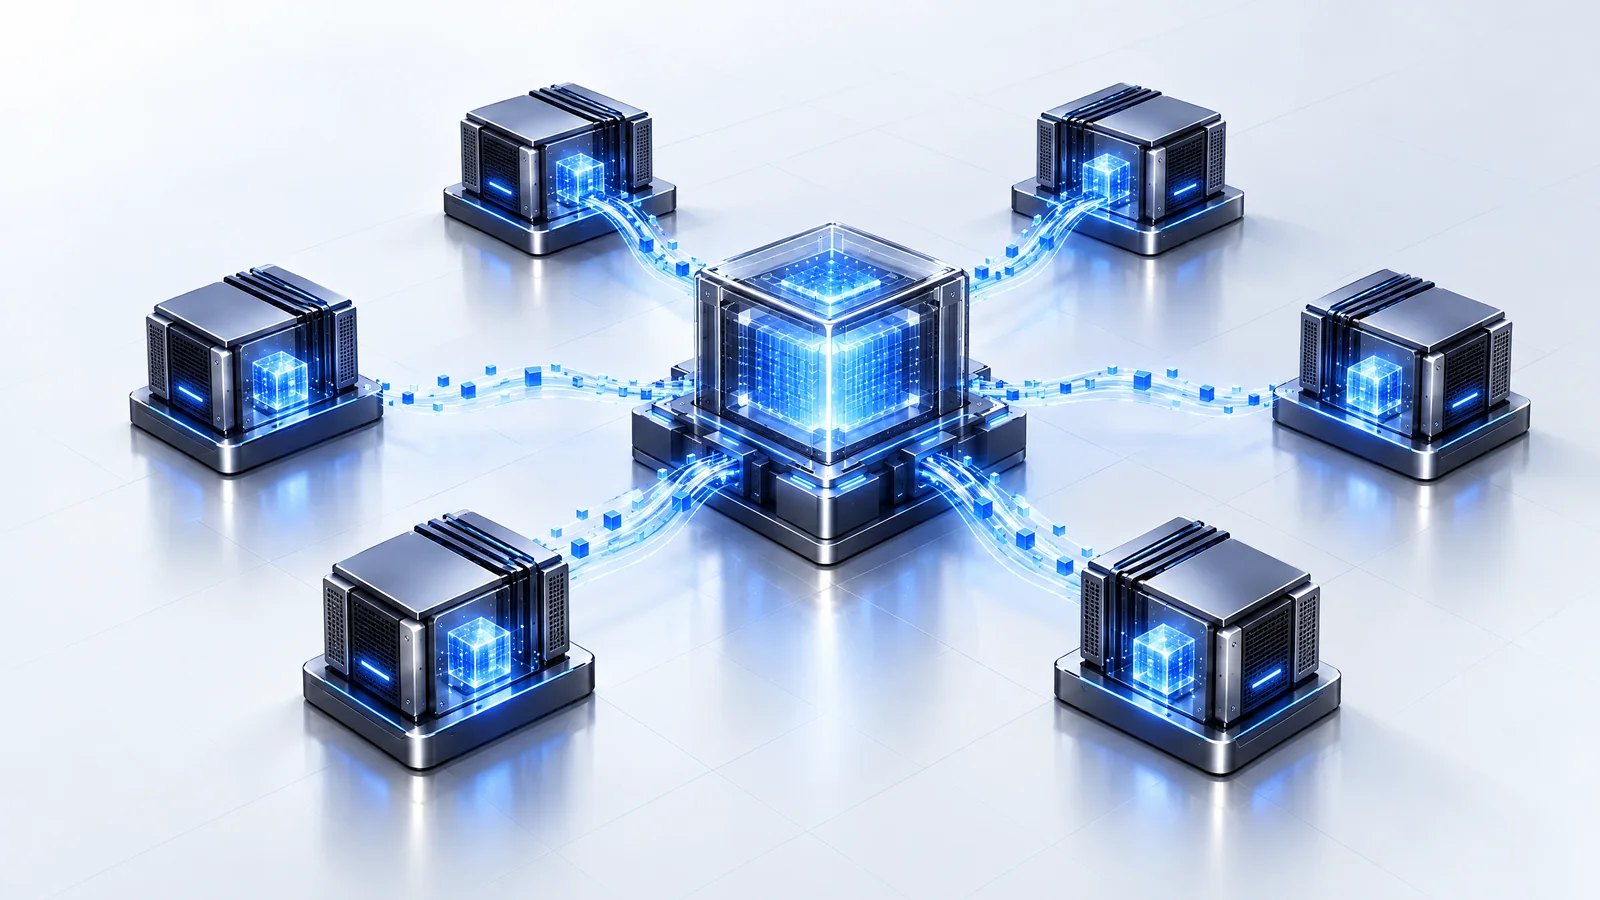
Federated learning (FL) is best understood as a way to move computation to distributed data, not as a privacy guarantee. Participants train locally and share model updates or related signals rather than automatically pooling raw records. That can reduce routine movement of sensitive data, but updates can reveal information; a trained model can memorize; a coordinator can be curious or compromised; and a participant can manipulate training. Privacy, security, statistical quality, and operational resilience therefore depend on the complete system around the learning algorithm, not on the word “federated.” 1 2 3
A useful production design begins with a specific question: who is protected from whom, against what information, and under which failure assumptions? A mobile application operator may want to keep individual user contributions hidden from its own training service. A hospital consortium may primarily need to avoid transferring patient records between institutions while protecting each organization’s interests. A regulated data owner may care about model outputs released to customers. These are different objectives. The same protocol cannot be assumed to solve them all.
This article examines two common architectures, their data and trust boundaries, and the engineering choices that turn a federated experiment into a defensible service. Its central practical point is simple: “data stays local” describes one property of a workflow. It does not establish that no one can infer facts about that data.
Choose the federation that matches the data and participants
Cross-device and cross-silo FL are often presented as variants of one algorithm. Operationally, they are different regimes. Cross-device systems involve many end-user devices such as phones, tablets, or sensors. A device may be offline, battery-constrained, intermittently connected, owned by an individual, or running an older software version. There can be a large eligible population, but only a fraction is available and suitable for any training round. The original FedAvg formulation was motivated by decentralized data on mobile devices and described local training followed by iterative model averaging, with communication as a principal constraint. 1
Cross-silo FL involves a smaller number of organizations, such as hospitals, banks, or research institutions. Each participant usually has a stable identity, more powerful compute, and a persistent connection. The organizations may hold large datasets and can negotiate contracts, audit procedures, and protocol expectations. Their data may be horizontally partitioned, where organizations hold different records with substantially similar features, or vertically partitioned, where organizations hold different attributes about overlapping people or entities. Horizontal federation lets each party train on a locally complete record set; vertical federation must deal with matching entities and coordinating computation across feature holders, which is usually more involved. 4
The distinction affects more than infrastructure. In cross-device FL, individual participants are often small and numerous, so sampling, dropout handling, and user-level privacy are prominent. In cross-silo FL, the number of organizations is comparatively limited, each can contribute a large volume, and a single participant may have substantial influence. A hospital with a rare patient population can shift the learned model in a way that would be less likely from any one phone. Conversely, a large population of devices does not imply strong privacy if the aggregation service observes each update or releases outputs that leak.
A product team should write down which parties are participants and what each can see. The coordinator might distribute a model, select clients, accept updates, aggregate them, and publish a new model. Participants can inspect their local input data and the model they receive; they may also know the current round and protocol configuration. The coordinator may be trusted, honest-but-curious, compromised, or actively malicious. Participants may be honest, faulty, or adversarial. A network observer may see metadata even when payloads are encrypted. The final model consumer may mount membership inference or extraction attacks. These roles should not be collapsed into a generic “attacker.”
Cross-silo contracts do not remove technical threats. A participant may submit corrupted updates, credentials can be stolen, and an operator may inspect unprotected contributions. Yet the stable and relatively small participant set can make identity vetting, secure enclaves, pairwise agreements, incident response, and independent audits more attainable. For cross-device, the service cannot practically assume that every endpoint is trusted or manually reviewed. It must tolerate churn, impose resource budgets, and use mechanisms designed for large populations and repeated rounds.
Federation also does not mean all data is physically confined forever. Model checkpoints, logs, debugging traces, cached batches, telemetry, crash reports, and evaluation exports can move sensitive information. Data locality must be a verifiable property of the entire pipeline, including the support and observability systems around training. If an engineer adds raw examples to a diagnostic upload to investigate a training failure, the central training code may be federated while the actual data path is not.
How a training round works—and where choice enters
A common synchronous round starts when the coordinator chooses a subset of eligible clients and sends them the current model and training instructions. Each selected client trains locally for some number of steps or epochs, calculates an update, and returns it. The coordinator combines updates into a new global model, then begins another round. FedAvg is a canonical iterative averaging approach: local model updates are weighted and aggregated to produce the shared state. 1
In a simplified form, let the current model parameters be wt. Client i performs local training on its data and returns w_i, or an update Δ_i = w_i − w_t. The server computes an aggregate using selected client weights p_i, often related to their local example counts: w(t+1) = w_t + Σ_i p_i Δ_i. This notation hides critical details. A service needs to define whether it receives model weights, gradients, deltas, compressed representations, or sufficient statistics; how client weights are obtained and validated; how many local steps are performed; and what happens when clients disappear. In some privacy designs, revealing exact participant dataset sizes is itself sensitive, so even the weighting rule needs review.
Local training reduces the frequency of communication. A device can execute multiple local steps before sending a contribution, which may be more bandwidth-efficient than synchronizing after every batch. But longer local training can make updates less comparable, particularly when participants have different data distributions. It also raises exposure to client-side manipulation: a malicious endpoint can modify its local training, fabricate a delta, or exploit differences between the broadcast model and its own computation. More local work is not automatically better simply because it saves network requests.
Client selection, often called client sampling or participant sampling, is both a systems mechanism and part of the statistical and privacy design. A cross-device service may select only clients meeting availability conditions—for instance, connected to an appropriate network, sufficiently charged, or idle. These conditions reduce disruption and failed uploads, but selection can bias who participates. Device availability correlates with geography, income, work schedules, connectivity, hardware, and patterns of use. If one group is rarely eligible at the chosen time, its data may be underrepresented even if its records exist on devices.
Sampling changes privacy accounting too. In differentially private training, the probability of a person’s participation and the number of times their contribution is included matter to the accumulated privacy loss. A privacy accountant must use the actual sampling and contribution assumptions, rather than a hoped-for eligibility rate. If the system retries participants, schedules cohorts with unequal probability, or selects devices using data-dependent criteria, the sampling model used by the guarantee may no longer describe production. A privacy claim needs to be checked against implemented selection and repeat-participation behavior, not only against a paper design.
In cross-silo systems, the phrase “client sampling” can be misleading. With a few organizations, each round may include most or all sites; one absent hospital may mean a substantially different population for that round. A protocol can still sample organizations, but the practical concern is often quorum, governance, and cohort composition rather than random draws from millions of interchangeable devices. If a consortium requires at least a minimum cohort, the training service should define what happens when the threshold is not reached: abort, wait, or proceed with a reduced set. Proceeding with fewer contributors can change both the privacy properties of aggregation and the representativeness of the update.
An asynchronous design can avoid waiting for a slow participant, but then the server may aggregate updates computed from different model versions. Stale updates may conflict with recent ones; a participant with unusual network latency can contribute at a different cadence. Asynchrony can improve utilization, but it complicates reproducibility, privacy accounting, and attribution of failures. The decision should follow measured availability and convergence behavior, not the assumption that a synchronous round is inherently too slow.
Non-IID data is a first-order design constraint
The central statistical challenge is that participants’ local datasets are often not independent samples from one common distribution. This is commonly described as non-identically distributed, or non-IID, data. It can arise because users have different preferences, hospitals serve different communities, and organizations collect different cases under different workflows. Dataset sizes can also be unbalanced: one site may have many more examples than another. The original FedAvg study treated unbalanced and non-IID distributions as defining conditions of the setting rather than an exceptional nuisance. 1
Suppose a typing model is trained across devices. One language community may be underrepresented among active devices. A hospital seeing a rare disease may hold a small but clinically important dataset. In a fraud consortium, institutions can differ in product mix and the kinds of transactions they label. Averaging local updates can optimize a global objective that gives more weight to participants with more examples, but that does not necessarily maximize performance for each participant or protect minority groups. “Global accuracy” can hide a poor error rate for a small region or a less common clinical workflow.
The design should define its target population before choosing aggregation weights. If the goal is average performance per record, record-weighted averaging may be reasonable. If the goal is equitable performance across institutions or users, participant-weighted objectives, constraints, or explicit subgroup metrics may matter. But participant weights can create their own challenges. A small organization might receive a disproportionately large influence if each silo is given equal weight. A device population can be overcounted if a single person uses many devices. The aggregation objective should be linked to a stated product or public-interest objective rather than selected merely because the framework supplies a default.
Increasing the number of local epochs can make a round more efficient, but the client updates may diverge farther from a shared direction when local distributions differ. Reducing local work or changing the learning rate can stabilize optimization, at the cost of more communication or slower progress. Proximal regularization and control variates are examples of algorithmic approaches explored to address heterogeneity, but a method effective on a benchmark does not guarantee improvement on a real population. 3 Teams should compare alternatives using realistic participant-level partitions and availability patterns.
The data partition itself deserves scrutiny. A benchmark with random IID splits can substantially understate the difficulty of an actual federation. A better simulation can partition by hospital, geography, user, device, time period, or institution, depending on the intended deployment. Each split answers a different question. A time-based split can expose concept drift; participant-based partitions expose client heterogeneity; geographic partitions can reveal regional gaps. A vertically partitioned problem also requires entity linkage across silos, so it is not enough to reuse a horizontal FL algorithm and assume the same privacy and systems properties. NIST’s discussion of horizontal and vertical partitioning underscores this architectural distinction. 4
Skew is not always a bug to eliminate. A user’s local preferences may be the signal that a product intends to personalize. In that case, a single global model might be the wrong abstraction. Teams can consider a shared representation with local adaptation, clustered models, personalization layers, or local fine-tuning. Each introduces trade-offs: local parameters may be harder to evaluate centrally; clustered models may reveal group membership; personalization can increase client compute and storage; and an organization may resist sharing a model whose performance is poor for its population. The product requirement should distinguish “one model for all” from “a shared starting point with local adaptation.”
Secure aggregation: hiding individual contributions from the coordinator
Encryption in transit protects messages from some network observers, but the server normally decrypts each update before aggregation. Secure aggregation changes what the server can observe. In broad terms, clients participate in a cryptographic protocol that lets the service compute an aggregate of their values without learning each value individually. The server can receive a sum or aggregate, while individual vectors remain hidden under the protocol’s assumptions. A widely used secure aggregation design was developed for high-dimensional client updates and explicitly considered dropout and malicious server settings. 2
Secure aggregation is valuable when the privacy goal is to prevent the coordinator from inspecting any one client’s update. It can reduce the risk that the service operator, a compromised analytics account, or a curious administrator reads a participant’s raw vector. It does not make the aggregate harmless. An aggregate over a very small cohort may still reveal an individual contribution, especially if the server can compare overlapping cohorts or issue repeated queries. The system needs cohort thresholds, controls on query composition, and an analysis of what aggregate outputs reveal.
The protocol is not magic confidentiality “at rest.” It depends on correct client and server implementations, authenticated protocol messages, cryptographic key handling, and a threat model. A hostile client may attempt to deviate; a malicious coordinator may send inconsistent models or manipulate cohort composition; clients may drop out after different protocol phases. Protocol robustness and dropout recovery matter because real devices disappear, and because a privacy mechanism that only works under perfect participation will fail in production. The original secure aggregation work explicitly designed for failure robustness and evaluated communication overhead at large vector dimensions. 2
Secure aggregation creates a tension with anomaly detection. If the server can only inspect a sum, it cannot simply compute an outlier score for every individual update. That can make some defenses against poisoning harder to apply. In practical deployments, this is not an argument to abandon privacy protections; it is a prompt to design compatible controls. Options include client-side clipping before cryptographic aggregation, trusted execution environments with carefully bounded access, robust aggregation protocols, verification of computation, or audit signals that disclose less than the full update. Each adds assumptions or cost, and none should be presented as a universal solution.
Secure aggregation does not automatically hide metadata. The coordinator may still see network addresses, timing, cohort membership, upload sizes, model versions, error codes, or the fact that an organization participated. Authentication and enrollment may connect an update to a persistent identity even if the vector is hidden. Differential privacy and cryptographic aggregation address different exposures: secure aggregation can conceal individual inputs from the aggregator, while differential privacy limits what released outputs reveal about an individual’s participation or data. They may be combined, but the guarantees and implementation requirements must be evaluated separately.
For cross-silo federation, secure aggregation may be paired with a trusted legal and operational agreement, but it is still important to ask what happens if one participant colludes with the coordinator. For cross-device training, the cohort may be larger, but dropouts and device compromise become more common engineering considerations. In either regime, privacy claims should specify the minimum cohort, tolerated dropout, whether identities are visible, and whether one server operator can manipulate rounds. Avoid saying “the server sees only the sum” without checking whether the protocol’s exact deployment has these properties under its stated assumptions.
Differential privacy: quantify the information released
Differential privacy (DP) is a mathematical framework that bounds how much a mechanism’s output can change when one person’s data is included or excluded under a defined neighboring-dataset relationship. It provides a way to reason about an adversary who can see the released result and knows other information. Unlike a statement that raw records are not uploaded, a DP guarantee addresses information in outputs. The value of that guarantee depends on the unit of protection, the parameters, the mechanism, and the accounting across repeated releases. NIST’s guidance emphasizes that practical DP implementations are subject to hazards as the mathematics is translated into software. 5
In a typical DP-SGD workflow, examples are sampled, gradients are computed, per-example gradients are clipped to a norm bound, clipped gradients are aggregated, and random noise is added. In federated training, a client-level or user-level variant may clip each client’s model update and add noise to the aggregate, often in concert with secure aggregation so the server does not see individual uncloaked updates. The distinction between record-level and user-level privacy matters. Protecting one example does not necessarily protect a person who contributes many examples; user-level DP treats a person’s entire contribution as the protected unit, which can require more noise or a different accounting design.
A DP guarantee is typically expressed through parameters such as epsilon and delta. These numbers do not have a context-free interpretation that automatically makes a system acceptable. A smaller epsilon generally corresponds to a stronger bound in a given setup, but comparisons require the same neighboring relation, sampling assumptions, mechanism, and accounting method. Delta is a failure probability term and should be selected with the protected population and release context in mind. Teams should report the privacy unit, parameters, accountant, sampling model, clipping rule, training steps, and releases. Merely publishing “DP enabled” is not a meaningful specification.
Noise reduces the ability of an observer to distinguish outputs from neighboring datasets, but it also perturbs the optimization signal. For small or highly heterogeneous cohorts, noise can dominate useful updates. The engineering task is to tune a privacy-utility point that meets a stated privacy objective and still achieves acceptable performance. If model utility is only measured on a large aggregate test set, a system may hide a severe loss for small participant groups. DP should be included in the same stratified evaluation as the baseline, and the privacy budget should be decided before training rather than retrospectively chosen to make a result appear acceptable.
Privacy loss composes. Repeated training rounds, model releases, evaluation queries, and multiple related tasks can collectively reveal more than any one output. The accountant must track the full sequence of mechanisms that touch a protected contribution. If a user can participate across many runs or opt into multiple model variants, their exposure may accumulate. A model update hidden with secure aggregation is not the same thing as a final model trained with DP; nor does adding noise to a final metric retroactively protect an earlier non-private checkpoint that has already been published.
Central DP and local DP make different trust trade-offs. In central DP, a trusted curator sees unnoised information or individual inputs before applying noise to outputs. This can provide higher utility at a given guarantee, but the curator must be trusted or protected by another mechanism. Local DP adds noise at or near the data source so the collector never sees the unperturbed contribution, but typically requires more noise to achieve a similar aggregate utility. Federated deployments can use secure aggregation to hide individual contributions and add noise to the aggregate, reducing reliance on a server that sees each update, but details depend on who generates and controls the noise and whether that party can cheat or remove it. The full threat model matters more than the DP label.
DP does not ensure that a model is fair, accurate, robust to poisoning, or safe to deploy. A valid guarantee can coexist with poor performance on a subgroup or an unsafe output. Nor does a DP guarantee protect against every form of disclosure unrelated to the protected unit, such as secret metadata exposed by a log or a person who intentionally contributes a unique fact. DP is one carefully scoped privacy control. NIST’s evaluation guidance calls attention to assessing the actual software and its hazards rather than treating the mathematical definition as proof that implementation is correct. 5
Update leakage is a realistic threat, not a theoretical footnote
Gradients and model deltas encode information about training. A reconstruction attacker can exploit a participant’s update together with the model and training assumptions to infer or reconstruct examples. The Deep Leakage from Gradients work demonstrated reconstruction of training data from shared gradients, including image and text examples in its studied settings. 6 NIST’s review of federated-learning privacy attacks similarly distinguishes attacks on updates during training from attacks on the trained model after the training process. 7
Attack feasibility varies. A one-step gradient from a small batch can leak more directly than an update produced after many local steps and mixed examples, but multiple steps are not a privacy guarantee. Update dimensionality, architecture, batch size, labels, model state, client behavior, and attacker knowledge can influence reconstruction. An attacker can be the central coordinator, another participant who sees broadcasts, a compromised training service, or an external party with access to stored updates. The relevant question is not whether a particular demonstration exactly matches production; it is whether the release boundary exposes enough information for a credible attacker under the intended threat model.
The model itself can also disclose. Membership inference asks whether a record or person was part of training. Model inversion seeks attributes or representative examples. Extraction attempts to recover memorized content or approximate the model. Such attacks can target the released model without seeing training updates. Restricting raw updates from the coordinator therefore does not alone ensure output privacy. NIST explicitly notes both update-targeting attacks and attacks on trained models, and identifies DP as a comprehensive approach for output privacy. 7
Several practical controls can reduce exposure, but their scope should be clear. Secure aggregation limits who sees an individual update. DP limits information revealed by outputs relative to a neighboring dataset. Limiting logs and retention reduces the number of copies available to attackers. Restricting model access and query rates may make attacks harder, although rate limits are not a formal privacy guarantee. Smaller models or reduced memorization can be useful, but they do not replace measurement. A service should test the actual deployed model and training protocol against attack scenarios, including repeated queries and auxiliary information that an adversary could realistically obtain.
A common failure is to assume that parameter deltas are anonymous because they lack obvious names or raw fields. If a client’s update is stored alongside an account identifier, timestamp, or cohort record, it is plainly linkable. Even absent direct identifiers, unusual update patterns or rare cohort timing may support linkage. Pseudonymization and encryption are useful controls but should not be conflated with anonymization or DP.
Poisoning and backdoors: contributors can alter the model
A participant can be adversarial as well as private. Data poisoning means corrupting local training examples or labels to influence the model. Model poisoning means manipulating the update directly, potentially without relying on the local examples. A backdoor is a targeted behavior that activates under a chosen trigger while ordinary validation performance remains acceptable. A malicious participant might aim to misclassify images with a visual mark, cause a text model to produce a selected continuation after a phrase, or degrade a particular population’s outcomes.
Federated aggregation creates a distinctive risk: the server often cannot inspect each local training example, and secure aggregation may hide the individual update. The research on backdooring federated learning showed model-replacement attacks in which a participant manipulates its contribution to introduce a backdoor into the jointly trained model, and described ways to evade anomaly defenses. 8 This does not mean every deployment is equally vulnerable; it means that “each client trains honestly” is an assumption that must be made explicit and defended where it matters.
Ordinary averaging is not a security filter. If a malicious participant can submit an arbitrary vector, the server’s weighted average can be shifted. If the participant can exploit the aggregation weight or a small cohort, the effect may be larger. A system should authenticate clients and verify model versions, but authentication only says who sent the update, not whether the update is benign. Rate limits and contribution caps constrain some abuse, yet they cannot establish that each update reflects legitimate training.
Robust aggregation approaches attempt to tolerate some malformed or adversarial contributions by downweighting outliers or combining updates in a robust way. Their guarantees typically depend on assumptions about the fraction and behavior of adversaries, the geometry of honest updates, and how similar honest clients are expected to be. In non-IID federations, legitimate minority participants may look like outliers. A detector trained on historical behavior can penalize a newly participating hospital or an unusual but important user population. Robustness thresholds that work on simulated independent attacks can fail when attackers collude, adapt to the defense, or distribute a subtle trigger across participants.
Secure aggregation can make per-client anomaly scoring unavailable by design. This is a direct privacy-security trade-off, not a reason to secretly retain updates outside the privacy protocol. If the use case needs robust defenses, options include protocol-level checks, cryptographic proofs for bounded computation, secure computation of selected statistics, enclaves with governance controls, trusted admission for cross-silo partners, and post-aggregation testing for suspicious behavior. Each option has a cost, an assumption, and a blind spot. An enclave shifts trust toward hardware and attestation; trusted partner admission does not prevent a compromised partner; aggregate tests may miss a trigger that affects a narrow subgroup.
Evaluation should include targeted behavior, not just average loss. A model can achieve excellent top-line accuracy and still contain a backdoor. Define plausible trigger or targeted failure cases with domain specialists, evaluate across rounds, and test on data from participants not used in training. Inspect clean performance, attack success under designed scenarios, subgroup impact, and recovery when suspicious clients are removed. A defense that removes all updates from a rare institution may appear robust while excluding the group the system was supposed to serve.
Threat modeling can make these trade-offs legible. Identify assets such as raw examples, client updates, model parameters, participant identity, cohort membership, and system credentials. Identify adversaries such as a curious coordinator, malicious participant, colluding participants, compromised endpoint, network observer, or model consumer. State capabilities: can the attacker choose data, control a client, observe broadcasts, replay rounds, submit many identities, or query the final model? State the goal: reconstruct a record, infer membership, alter general behavior, embed a targeted backdoor, or deny service. Then map each mitigation to the specific capability it addresses. “Encrypted” without naming which party lacks the key is not a threat model.
Communication, availability, and reproducibility
Communication costs are not simply the number of bytes in one model. A production estimate should include downlink model distribution, uplink updates, cryptographic protocol messages, retries, metadata, model versioning, and the number of rounds needed to converge. A compression method that shrinks each update can save bandwidth but alter optimization or privacy behavior. Quantization can reduce precision; sparsification can reveal which coordinates were selected; differential privacy noise may interact with compression; secure aggregation may require a compatible fixed-point representation and careful overflow bounds.
Round duration can be limited by the slowest required participant in synchronous systems. Cross-device populations have variable network and compute conditions, so waiting for every selected device can make training fragile. Dropout-tolerant secure aggregation can help, but reaching a minimum cohort and completing protocol stages still require coordination. For cross-silo systems, a single site’s maintenance window, governance hold, or delayed data pipeline can block the whole round. The orchestration layer needs explicit timeouts, retry policy, cohort thresholds, and a way to resume without double-counting contributions.
Systems should distinguish eligible clients, selected clients, clients that downloaded the model, clients that trained, and clients whose updates passed protocol validation. A single “participants” counter masks failures. Track aggregate completion rates and latency distributions without unnecessarily collecting sensitive per-user histories. If operational metrics are linked to long-lived identifiers, that metadata may become a new privacy store. Telemetry itself should follow data minimization, access controls, and retention limits.
Reproducibility is harder when the training population changes each round. Record the model version, code and dependency hashes, protocol configuration, cohort-size summaries, sampling policy, privacy accountant state, and aggregate evaluation. Avoid storing raw updates if the security architecture promises that the coordinator cannot inspect them. A reproducible run does not require every sensitive input to be centrally logged; it requires enough safe metadata to reconstruct the procedure and diagnose behavior within the approved boundary.
Client software needs secure update and rollback paths. A malicious or buggy model can consume excessive power, use unexpected local data, or create a denial of service. A client should validate that a received training job is authorized, bounded in resource use, and compatible with its software policy. The coordinator should reject stale or malformed updates and defend against replay. For cross-device systems, version skew means not all participants execute identical code at once. A staged rollout and compatibility plan can prevent silent mixing of updates produced by different model definitions.
Non-IID shifts can be temporal as well as cross-sectional. User behavior changes after product releases; hospitals change coding practices; a financial institution alters fraud controls. A model may become stale even when training converges. Federated evaluation must track time and site-level distribution shifts while respecting privacy boundaries. Aggregate metrics can miss a newly failing site, while highly granular reports may expose information. The system owner needs a minimum reporting group size or other disclosure control, and a plan to investigate a signal without reflexively requesting row-level data.
A production evaluation plan
Start with a centralized reference model only where lawful and appropriate. Its role is diagnostic: it can help estimate the performance ceiling or isolate algorithmic effects, but it may not be a viable or acceptable deployment. Compare that reference with local-only models and federated alternatives on the same realistic partitions. If the federated model does not improve on the relevant baseline, the added complexity may not be justified. The baseline should be selected to answer a question, not to advertise federation as an automatic performance advantage.
Use participant-aware train, validation, and test partitions. If a device or hospital contributes to both training and test data, performance can look better than the experience on a new participant. Hold out some organizations or users when generalization to unseen participants is important. Keep temporal holdouts when future deployment differs from historical data. For personalized systems, report both the shared initialization and the post-personalization result, and make clear how many local examples were needed for the latter.
Measure more than one aggregate score. Report suitable task-specific metrics, calibration, error costs, and performance across relevant groups and sites. In a clinical setting, a false negative and a false positive can have different consequences; in a fraud system, false alarms impose investigation costs. Evaluate slices only when sample sizes and disclosure risk allow it. A global average can conceal unequal harms, but an unsafe dashboard of tiny groups is not a solution. Establish reporting thresholds and carefully designed statistical controls before inspection begins.
Evaluate convergence under realistic participation. Vary the number of selected clients, availability, dropout, client weights, local computation, and distribution skew. Simulate slow or absent sites and test the actual secure aggregation threshold. Run sensitivity analyses for changes in participant composition. If model quality collapses when one large site is absent, that dependency is part of the product risk. If a user’s chance of selection differs by time zone or hardware, measure who is systematically excluded.
Evaluate privacy as an attacker-facing property. State whether you claim that individual updates are hidden from the server, that the final model satisfies a DP guarantee, that raw records remain in a particular jurisdiction, or some combination. Test gradient reconstruction and membership-inference scenarios appropriate to the model. Review any persistent update stores, logging systems, and model-release interfaces. Confirm privacy accounting against actual participation and retraining frequency. Treat observed attack failure as evidence about the evaluated setup, not proof that future or stronger attacks are impossible.
Evaluate security with both generic and domain-specific poisoning. Build a red-team plan that includes malicious local data, direct update manipulation, compromised credentials, colluding participants, replay, and model replacement attempts where relevant. Track both clean utility and targeted attack success. Test defenses against adaptive attackers and under realistic non-IID conditions. Document what the system cannot observe because of secure aggregation. If the answer is “the protocol deliberately hides it,” make sure the remaining security controls are adequate for the risk.
Before deployment, establish release gates. A gate can require acceptable task performance, minimum subgroup performance, DP budget within policy, successful secure-aggregation completion at the planned cohort size, passing robustness tests, no unresolved critical leakage in logs, and a rollback plan. The numeric thresholds should come from the product’s risk tolerance, applicable obligations, and empirically justified use case; there is no universal threshold that can responsibly be copied across domains. Record who approved exceptions and which assumptions they accepted.
Choosing deployment patterns
Choose cross-device FL when the data naturally resides on a large number of user-controlled devices and the product can train within the device’s resource, connectivity, and consent constraints. It can be suitable for aggregate improvement of keyboard suggestions or on-device personalization, where the application has a meaningful reason to learn from local behavior without routinely uploading examples. But the system must account for partial participation, device diversity, user-level privacy, malicious clients, and update leakage. If the objective is simply to train on server-held logs, labeling the job federated does not create a benefit.
Choose cross-silo FL when independent organizations hold relevant records and pooling is legally, contractually, or operationally unacceptable, while the organizations can align on schemas, labels, protocol operation, and governance. This can support collaboration across hospitals or financial institutions. Before model training, test whether data is horizontally or vertically partitioned and whether entity matching is needed. If no common target definition or compatible data quality exists, a federation protocol will faithfully combine inconsistent inputs rather than resolve the disagreement. NIST describes the additional linkage challenge in vertical partitioning. 4
Sometimes the right design is not federated learning. A federated analytics query, secure multiparty computation, a trusted research environment, synthetic data for development, or carefully governed centralized training may better fit the objective. If the goal is a single count or mean, training a neural network may add needless attack surface. If the data cannot be joined consistently, federated optimization may not answer the question. If the parties cannot sustain protocol maintenance or incident response, a theoretically elegant system may fail operationally.
A layered design often provides the strongest practical position. Keep raw training records at the participant; use secure aggregation to prevent inspection of individual contributions; apply user-level DP to bound information in the released model where required; authenticate participants and constrain update behavior; validate against poisoning and privacy attacks; and govern the complete data path, including telemetry and checkpoints. The layers address distinct risks. Secure aggregation is not DP; DP is not access control; access control is not poisoning defense; and no single control makes the rest redundant. 2 5 8
The deployment choice should be tied to the adversary. If the operator is trusted but raw records must remain at institutions, locality controls and rigorous governance may be primary, though update leakage still matters. If the operator itself must not see individual updates, secure aggregation is central. If the final model will be public or broadly queried, output privacy and memorization controls become more important. If a participant can be hostile, authenticated membership and poisoning-resistant evaluation need attention. These requirements can conflict, so state priorities and residual risks rather than calling the entire system “privacy preserving” without qualification.
Implementation checks and common failure modes
Before the first training run, write down the protected privacy unit and neighboring-dataset definition. Is the guarantee for one record, one user across all their local records, one device, or one organization? Then identify what each party observes at every stage: training job, model download, client update, aggregate, checkpoint, metric, and final prediction. A diagram of data and trust boundaries often reveals an unexpected export or administrator access path that a model-level description misses.
Specify a protocol contract. Define model and update formats, allowed client versions, sampling and retry policy, weighting, local training budget, secure aggregation threshold, dropout behavior, clipping rule, DP noise and accountant, output release schedule, and retention. State whether updates can be reused for debugging and who can access aggregate checkpoints. A protocol that is secure only when each client follows an unwritten expectation is not production-ready. Version these choices alongside software so that privacy analysis tracks actual behavior.
Verify implementation, not just configuration. Check that raw examples do not enter central logs, crash reports, or object storage. Confirm that encryption keys are scoped and rotated appropriately, that the server cannot decrypt individual updates if that is the stated claim, and that protocol code enforces cohort and dropout assumptions. Confirm clipping happens at the intended unit and before the step at which its sensitivity is claimed. Check that DP noise is generated and applied in the documented location, that the accountant counts every release, and that test and staging systems do not publish unprotected checkpoints.
Test failure paths. What does a client do if it receives a stale model? Can a retry submit the same update twice? What if the secure aggregation protocol fails after a subset has committed? Is the aggregate discarded, or can a partial cohort be recovered safely? Does the server accidentally fall back to plaintext aggregation when cryptography fails? A fail-open fallback is especially dangerous: it may preserve availability while silently invalidating the privacy design. Prefer an explicit, observable stop with a safe retry over invisible loss of protection.
Test privacy and security assumptions in adversarial conditions. Can a coordinator make two nearly identical cohort queries and subtract aggregates to isolate a contribution? Can a malicious client claim an inflated data count? Can a participant send a vector with unusual magnitude or a targeted change? Can an attacker enroll multiple identities? Does a diagnostic endpoint return per-client status that enables linkage? Can an operator export an intermediate checkpoint? Secure aggregation thresholds and DP may limit some of these attacks, but controls must be evaluated against the actual protocol.
Common failure mode one is equating data residency with privacy. A model update is derived from local data and can leak; outputs can memorize; metadata can identify a participant. The remedy is to identify release surfaces and choose protections for each, with a clear statement of what the controls do not cover. Common failure mode two is treating DP as a switch. A DP library can be configured with the wrong privacy unit, an incorrect sampling assumption, or an untracked set of releases. The remedy is a reproducible privacy-accounting record and independent review of the guarantee.
Common failure mode three is reporting only pooled performance. A large site can mask a poor small-site result; selection can exclude particular users; DP noise can disproportionately harm a rare subgroup. The remedy is participant- and group-aware evaluation with safe reporting. Common failure mode four is assuming secure aggregation prevents malicious behavior. It hides updates from the aggregator but can also make suspicious updates harder to inspect. The remedy is a defense plan compatible with the chosen visibility boundary, plus controlled admission or robust protocol checks where suitable.
Common failure mode five is optimizing bytes before measuring the whole training cycle. Compression may reduce each upload but require more rounds, increase protocol complexity, or harm utility. The remedy is to benchmark end-to-end time, bytes, device energy, success rate, and model quality under realistic availability. Common failure mode six is treating a successful paper prototype as a sustainable service. Production needs key rotation, client version support, audits, incident response, governance, monitoring, and retraining policy. Assign owners and budget for those operations before promising the system’s privacy or uptime properties.
Finally, maintain a model and privacy change log. A new architecture, update representation, sampling schedule, number of training rounds, cohort size, or release pattern can change the threat profile. A seemingly small change can invalidate a DP accountant assumption or make updates easier to interpret. Require review when a change affects protected units, trust boundaries, aggregation, or output access. Retire old models and intermediate checkpoints under a documented policy; deleting raw training data does not erase information that may already be encoded in a model or retained in an update archive.
The practical standard
Federated learning is useful when distributed data, institutional boundaries, or device-local computation make centralized collection undesirable or infeasible. It can minimize routine data transfer and enable collaboration that otherwise would not happen. It also creates a networked training system with cryptographic, statistical, and operational failure modes. Data locality is a design property; privacy is a claim that must be scoped and supported.
A defensible system describes its federation type, data partition, participation process, threat model, update visibility, privacy unit, output guarantee, poisoning controls, evaluation coverage, and residual risks. It shows that model quality holds across the populations that matter, and that the protocol behaves correctly when clients drop out or fail. It tests leakage from both updates and trained outputs. It accounts for repeated releases and uses secure aggregation where the coordinator must not inspect individual contributions. It treats adversarial participants as a possibility rather than an impossibility.
The right production question is therefore not “Is this federated?” It is: “What can each party learn or change, what guarantees hold under which assumptions, and what evidence shows that this particular deployment meets its purpose?” Answering that question turns a fashionable architecture into an accountable system—and makes the limitations visible before they become an incident.
References
[1] Communication-Efficient Learning of Deep Networks from Decentralized Data [2] Practical Secure Aggregation for Privacy-Preserving Machine Learning [3] Advances and Open Problems in Federated Learning [4] Data Distribution in Privacy-Preserving Federated Learning [5] Guidelines for Evaluating Differential Privacy Guarantees [6] Deep Leakage from Gradients [7] Privacy Attacks in Federated Learning [8] How To Backdoor Federated Learning
Synthetic Data for LLM Testing: Coverage, Contamination, and Privacy
Design synthetic test data that expands LLM evaluation coverage without hiding leakage, privacy risk, or distribution gaps.
On-Device AI Systems: Quantization, Privacy, Updates, and Evaluation
Plan on-device model deployment around quantization quality, hardware limits, privacy boundaries, release updates, and evaluation.
Multimodal AI in Production: Evaluation, Latency, and Safety Across Modalities
Engineer reliable text, image, audio, and video AI workflows with modality-aware evaluation, safety, and operations.